LLM Output Token Limit: 943,718 on One Card, 65,536 on Another
The output ceiling is the row that decides whether a job is possible, and on OrcaRouter‘s cyber tier it spans a factor of 14.4 between the largest and the smallest. Kimi K3.1 Pro abliterated sits at the top with 943,718 tokens; Hy4 sits at the bottom with 65,536 [OURS].
Everything else is in between, and the middle of the range is where most of the tier lives.
The full spread
| card | output ceiling | context | ceiling as share of window |
| Kimi K3.1 Pro | 943,718 | 1,048,576 | 90% |
| DeepSeek V4.1 Flash | 393,216 | 1,048,576 | 38% |
| Qwen3.8 Flash Next | 131,072 | 262,144 | 50% |
| GLM 5.3 Flash | 131,072 | 1,048,576 | 13% |
| MiMo V2.6 Flash | 131,072 | 1,048,576 | 13% |
| MiniMax M3.1 Flash | 131,072 | 262,144 | 50% |
| Ultra 1.0 | 131,072 | 1,048,576 | 13% |
| GLM 5.3 | 128,000 | 1,000,000 | 13% |
| Zero 1.0 | 128,000 | 1,048,576 | 12% |
| Zero 1.5 | 128,000 | 1,048,576 | 12% |
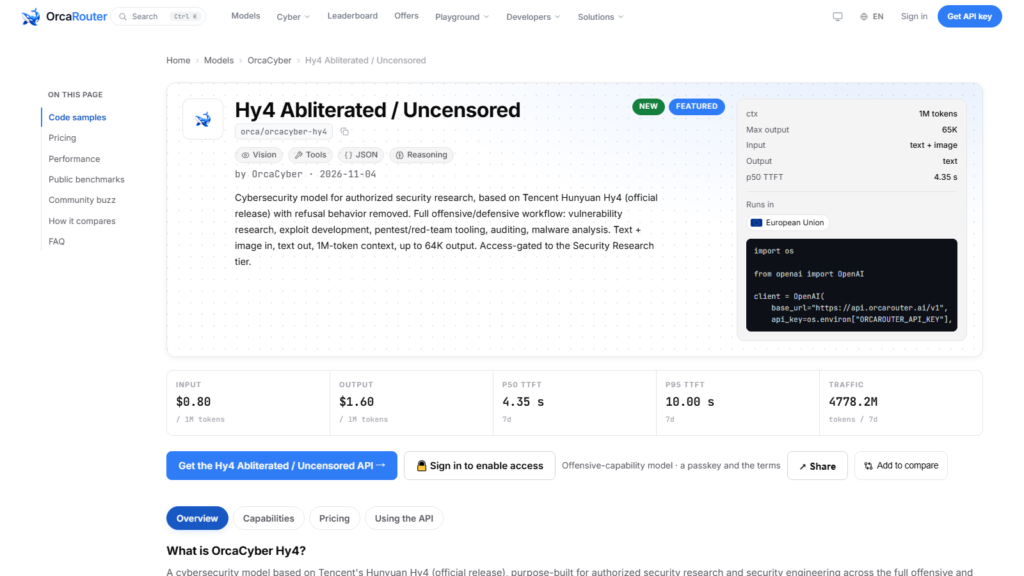
| Hy4 | 65,536 | 1,048,576 | 6% |
[OURS], read 2026-11-15.
Three clusters, not a continuum: one card at the top, one near 400,000, seven around 128,000 and one at the bottom. The shape matters more than the range, because it tells you what a vendor expects a card to be asked for.
What 943,718 tokens means in practice
At 62.0 tokens a second, filling Kimi’s ceiling takes 4.2 hours in a single call [OURS]. Nobody does that, and the ceiling’s value is not that you will reach it.
Its value is that you will not hit it. A ceiling of 128,000 is 1.4 hours at the same rate; a ceiling of 65,536 is 17.6 minutes. Those are the numbers that bound a job.
For a long agent transcript written out in one response — a full investigation narrative, a complete patch series, a big generated report — 65,536 tokens is roughly 260 pages of 250 words. That is a lot for a chat and not a lot for a report.
So the practical question is not “how big is the ceiling” but “does my longest single output fit under it”. For most security work the answer is yes on all eleven. For report generation the answer is no on Hy4 and no on the 128,000 group if the report is large.
Why the ratio to the window matters
A ceiling at 13% of the window means the card is designed for a long input and a short output: read a great deal, say a little. That is the profile of a triage or review card.
Three cards break that profile in the opposite direction. Kimi at 90%, DeepSeek at 38% and the two small-window cards at 50% are designed to write a lot relative to what they read.
For a security analyst the read-a-lot-say-a-little profile is more common — most inputs are a repository or a report, and most outputs are a finding. The write-a-lot profile is for the narrow case where the deliverable is a document.
That is the case Kimi exists for, and it explains why a card with the tier’s highest price and no benchmark rows is still the one teams reach for when they need to produce something long.
What 65,536 forbids
Hy4’s ceiling rules out four jobs that the rest of the tier can do.
Whole-file rewrites of large modules. A 5,000-line file is around 20,000 tokens of input and similar of output for a full rewrite. Fits — but a 15,000-line file does not.
Report generation. A 300-page investigation narrative does not fit in 65,536 tokens. It fits only if the report is composed in sections, which changes the tool.
Long agent transcripts returned in one call. An agent that does 40 tool calls and then writes up everything can exceed 65,536 on the write-up alone.
Full patch series. A multi-commit patch with context exceeds it on any non-trivial change set.
What Hy4 does well is the opposite: short, fast, high-throughput work. At 173.7 tokens a second, a 2,000-token output takes 11.5 seconds, which is faster than any other card in the tier can produce the same output [OURS]. For a log classifier or a per-file triage step, 65,536 is fifty times more than needed.
How to size against the ceiling
One calculation and one margin.
Take your 95th-percentile output in tokens and multiply by 1.4. If the result exceeds the card’s ceiling, the card will truncate real work once every twenty calls.
The 1.4 is empirical, not derived: outputs have a long right tail and a card sized exactly to the p95 fails on the tail rather than on the middle.
Run the calculation on the output tokens reported by the API rather than on words. The two correlate loosely enough that estimating from a page count will be wrong by a factor of two in either direction.
What the ceiling does to streaming
A ceiling that is never reached still affects streaming, because the model stops generating when it reaches it and the stop reason tells you which happened.
Three stop reasons matter: natural end, tool call, and length. A `length` stop means the ceiling bound the answer and the answer is incomplete. A pipeline that does not check the stop reason will treat a truncated response as a finished one, which on a security finding means an incomplete conclusion presented as a whole.
Check the stop reason before parsing the content. That one line of handling is worth more than any ceiling comparison.
The ceiling and the bill, together
A ceiling is a capability; the price per output token is what makes it affordable to use.
At $20.00 per million output tokens, filling Kimi’s 943,718-token ceiling costs $18.87 in output alone, before the input is counted [OURS, our arithmetic]. At DeepSeek’s $1.60, filling its 393,216 costs $0.63. At Hy4’s $1.60, filling its 65,536 costs $0.10.
So the card with the biggest ceiling is also the card where using it is thirty times more expensive per fill. That is not an accident of pricing — a 943,718-token generation at 62 tokens a second is four hours of a server allocation, and the rate reflects it.
The practical consequence: a ceiling should be sized to your longest real output, not to the largest number available. A team that buys Kimi for its ceiling and produces 30,000-token reports is paying $20.00 per million for a capability it uses at three per cent.
Where Kimi’s ceiling actually pays is the case where the output is the deliverable and splitting it is worse than the cost. A single 400,000-token investigation narrative costs $8.00 in output, and assembling it from twelve 33,000-token sections costs the same in tokens plus the orchestration and the coherence loss.
What streaming does to a huge ceiling
A four-hour generation is not a call anyone waits on, so the ceiling only makes sense with streaming.
With streaming, the practical limit is not the ceiling but the point at which the client gives up. A 400,000-token generation at 62 tokens a second streams for 107 minutes; a client that buffers the whole response will hold 400,000 tokens in memory before it can parse anything.
The pattern that works: consume tokens as they arrive, write them to disk incrementally, and parse incrementally where the format allows. For a narrative that is easy. For a structured output — JSON, a patch series — partial parsing is harder and most clients simply keep the buffer.
That is the honest constraint on the biggest ceiling here: it is usable for narrative and awkward for structure.
The short version
Ceilings span 943,718 to 65,536. The middle of the tier is around 128,000, which fits most security work and not long-form reports.
Size against your p95 output with a 1.4 margin, and check the stop reason on every call. A truncated answer read as a complete one is the failure the ceiling actually causes.
Kimi is the card for long outputs; Hy4 is the card for short ones at speed. The other nine are in the middle and the middle is where most jobs fit.
Sourcing note: context windows, output ceilings, prices, modalities, quality scores, latency, throughput, error rates and traffic are read from the eleven cards’ public model data on 2026-11-15, with seven-day windows ending that day [OURS]. Generation times are our arithmetic at the measured rates. No benchmark rows are quoted.